

Inspect the scans first
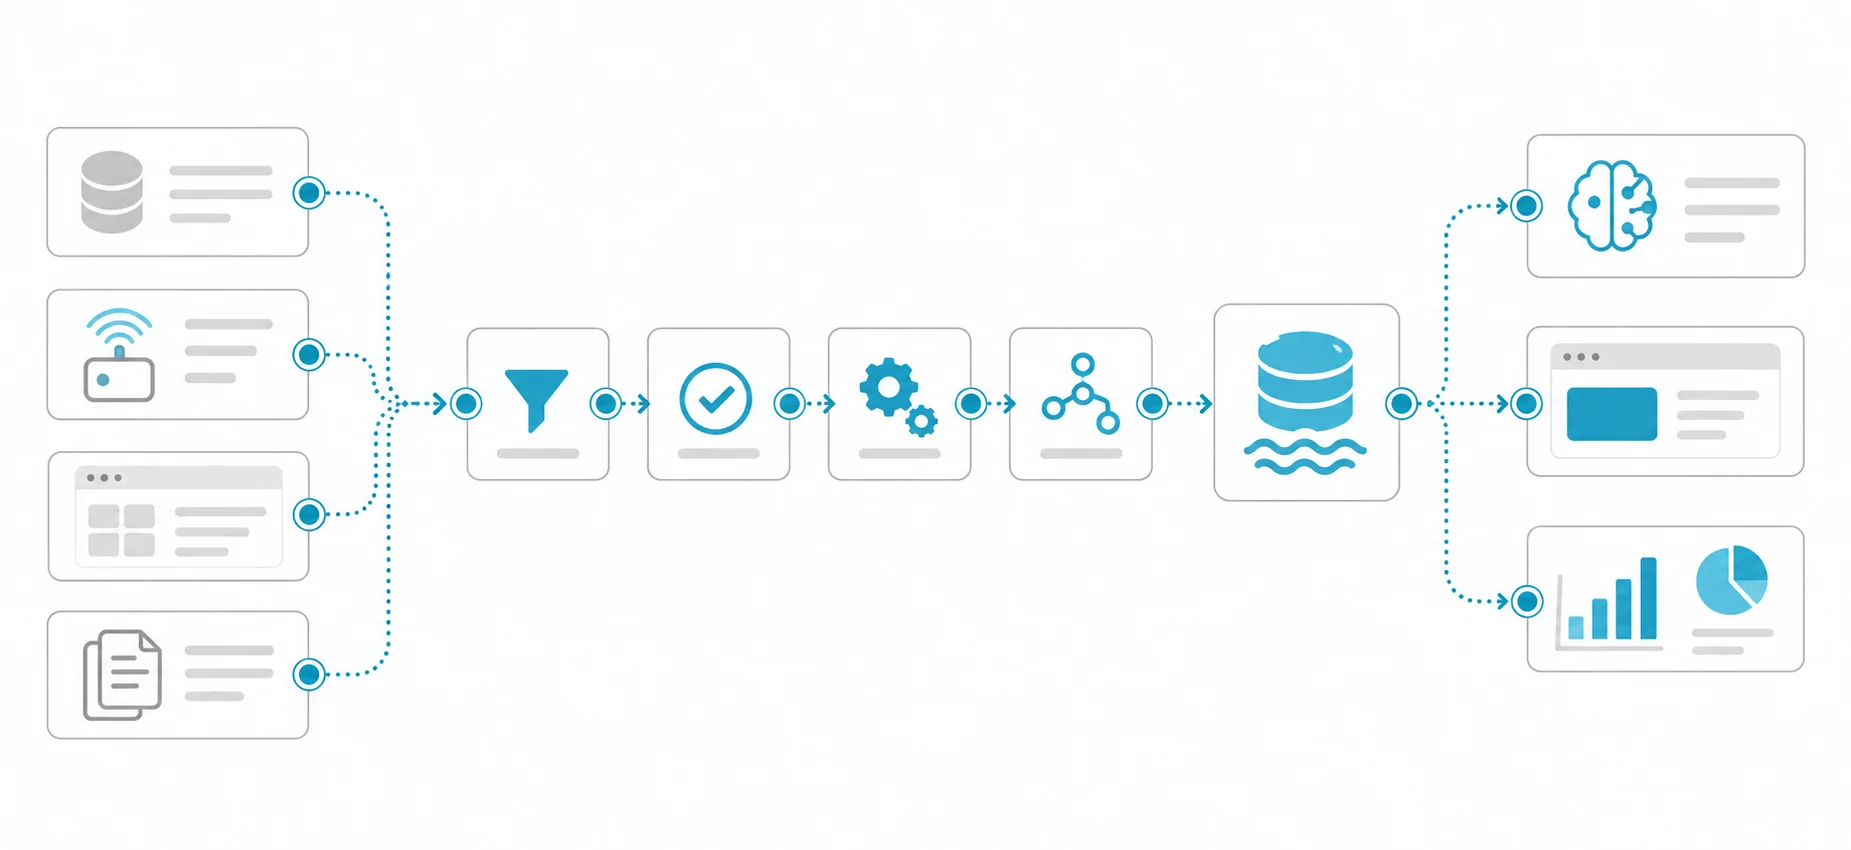
Separate digital PDFs with selectable text from image-only pages. Sample pages across scanners, dates, languages, and document types. Record skew, blur, cropped margins, faint handwriting, stamps, rotated pages, and low contrast. A uniform OCR pipeline may work for typed pages while silently losing handwritten approvals or tiny footnotes. Reject unreadable scans into a remediation queue instead of indexing empty or invented text. Keep the original page image available for verification; extracted text is a derived representation of evidence.
Extract structure with provenance
A document-analysis service can return words, lines, paragraphs, tables, page numbers, and positions; Microsoft's Document Intelligence layout documentation describes those elements. Preserve document ID, page, bounding region, extraction method, and confidence or review status with each passage. Azure AI Search's OCR skill can extract text from images, including images embedded in PDFs. Verify the supported input and service configuration for your deployment. A citation should open the page and ideally highlight the passage, not merely name a file.
Set quality gates
Create a manually transcribed sample of representative pages. Compare OCR output on names, amounts, dates, section headings, table headers, and negation words. Character accuracy alone can hide a dangerous error: changing 'not approved' to 'approved' alters a policy decision while affecting few characters. Require human review for pages below a quality threshold, missing expected fields, or implausible totals. Store corrected text as a separate version with reviewer and reason; do not overwrite the raw OCR output without a trail.
A claims-file example
Suppose an insurer receives scanned claim packets with a cover form, repair estimate, and handwritten note. The user asks which repairs were approved. The system must connect the note and estimate to the same packet, distinguish estimate from approval, and cite the page where approval is stated. If the handwriting is uncertain, answer with the reliable typed evidence and flag that approval requires manual inspection. A plausible number drawn from the estimate is not a grounded approval answer.
Test retrieval after OCR
Split text at document and section boundaries while retaining page references. Build questions whose answers depend on small qualifiers, tables, and multiple pages. Score whether the correct passage is retrieved and whether the answer faithfully uses it. Track OCR rejection rate and correction time as operational metrics. Reprocess only affected documents when OCR settings change, and compare their retrieved answers before replacing the old index. Retrieval quality cannot exceed the quality of the page transcription it receives. OCR quality checks before indexing are part of how we build RAG and semantic search solutions over scanned archives.
Technical references: Microsoft Document Intelligence layout, Azure AI Search OCR skill. Related guide. Check the cited documentation against your own data, permissions and release version before applying this design.